Speechify is pricey, but it’s also completely transformed how I digest information
Original Article Summary
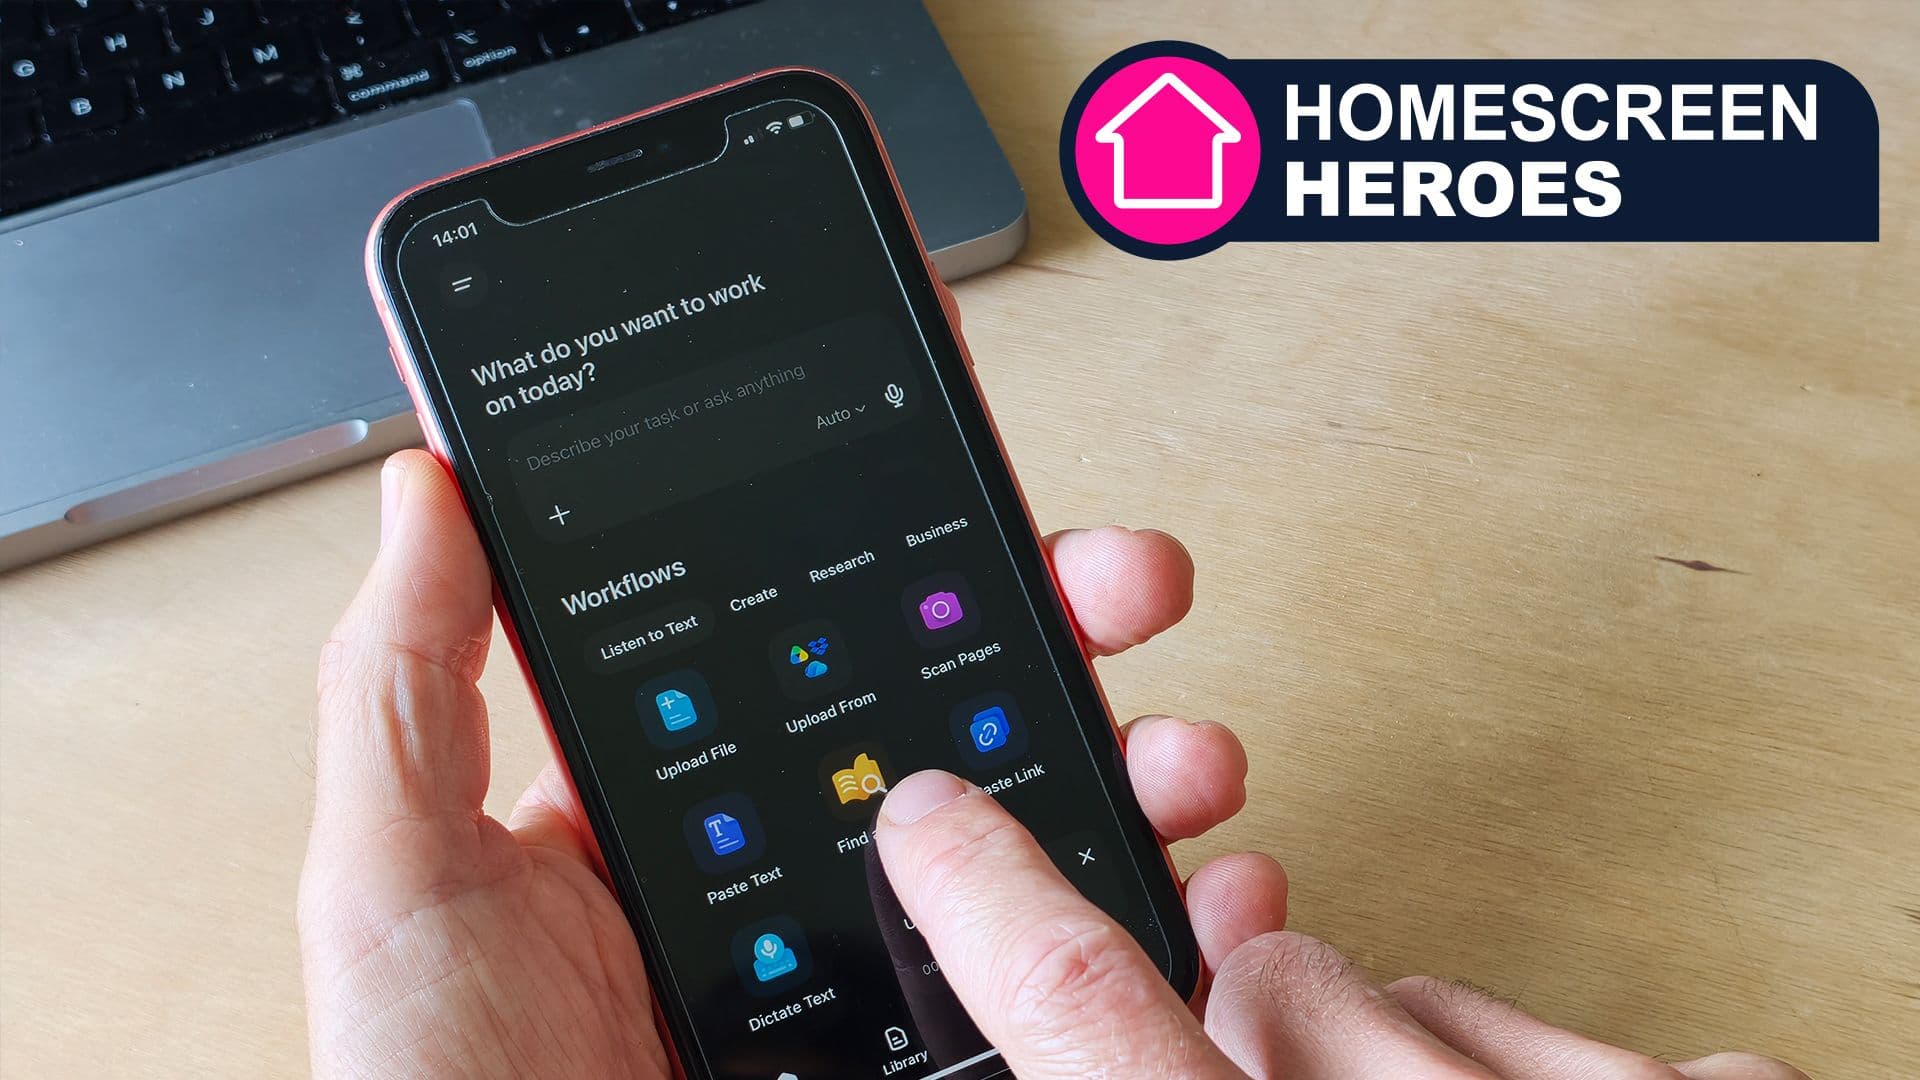
Homescreen Heroes: Speechify can read out documents, images, websites, and more
Read full article at TechRadar✨Our Analysis
Speechify's premium pricing model, which many reviewers describe as pricey, completely transforms how users digest information by reading out documents, images, and entire webpages. For website owners, this means a new class of AI‑driven readers will be crawling your site more aggressively, pulling full‑text content to feed into Speechify’s text‑to‑speech engine. Because Speechify can process visual elements like images and PDFs, pages that were previously safe from plain‑text scraping are now exposed, potentially increasing bandwidth usage and affecting SEO if duplicate audio content appears elsewhere. Moreover, the service’s willingness to pay for premium access may encourage deeper indexing of paywalled or subscriber‑only sections, raising concerns about content control and attribution. **Actionable tips:** 1. Update your llms.txt to explicitly list Speechify’s crawler user‑agents (e.g., `User-Agent: SpeechifyBot`) and decide whether to `Allow:` or `Disallow:` specific paths, especially for premium or copyrighted material. 2. Deploy real‑time bot analytics (e.g., log‑based detection or a WAF rule) to monitor Speechify traffic spikes and set rate limits to protect server resources. 3. Provide structured data (schema.org `Article` or `AudioObject`) so that Speechify can generate accurate audio renditions without over‑scraping, improving user experience while keeping your content under control.
Track AI Bots on Your Website
See which AI crawlers like ChatGPT, Claude, and Gemini are visiting your site. Get real-time analytics and actionable insights.
Start Tracking Free →